看图判断
截图交给 Jev 直接判,省掉先识别再判断两步。
痛点
截图、照片要做判断时,原来要先识别成文字才能处理,这中间多了一道工序、多了一份成本和延迟,文字识别这一步本身又会引入新的幻觉。截图本来就够看明白的事,硬是被拆成两步。
Jev 判断什么
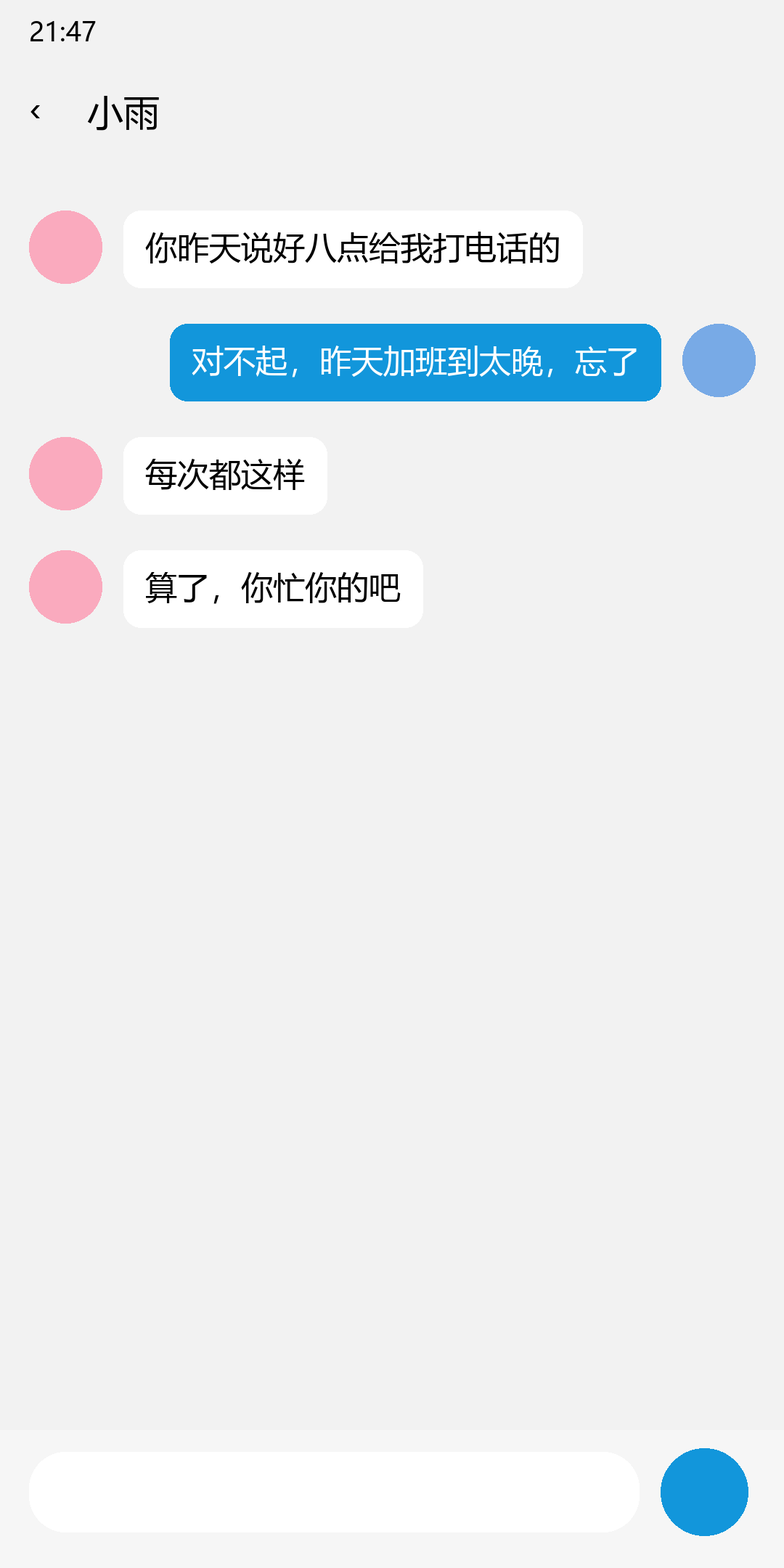
这次给 Jev 的 state 是 {"app": "聊天软件截图", "screenshot": "chat-shot"},screenshot 是图片资源,三道题并行判。
题目 last_sender 是 Choice 题型,问 screenshot 里最底下那条消息是谁发的,选项 {"them": "对方(左侧气泡)", "me": "我(右侧气泡)"}。这次返回 choice 是 them,对应概率 them=1.0、me=0.0,置信度 1.0。代码侧直接读 choice 拿到 "them",对应概率在置信度不够时做兜底。
题目 upset 是 Noul 题型,问 screenshot 里的对方是不是对我不满。这次返回「是」的概率 0.95;Noul 题型返回的是「是」这一侧的概率,越接近 1 越倾向「是」。代码侧按这个概率跟自己设的阈值比。
题目 input_box 是 Box 题型,问 screenshot 底部那条消息输入框的位置。这次返回框的坐标 上边 0.92、下边 0.98、左边 0.04、右边 0.83,都是占图片宽高的比例,置信度 0.89。代码侧拿这四个值就能换算成像素坐标,做裁图、蒙版都行。Box 题型现在只有 Jev 1.14 有。
和大模型怎么配合
Jev 先判,代码按结果再分流。last_sender 这种结论明确、置信度又高的(这次 1.0),走规则不用调大模型。upset 这种主观题,置信度高且远超自己阈值的(这次 0.95),按 Noul 的概率直接走处置(比如自动标情绪警示);靠近阈值或置信度不够的,把 state 和 Jev 的判断一起给 LLM 复核,或者直接推给人工。input_box 拿到坐标后,下游的贴表情、读屏这些动作可以直接对图片区域做,比把整张图丢给大模型省。
这次调用耗时 1700 毫秒,花费 0.00014868 美元,按这个算每 1000 次约 0.1487 美元。Jev 按输入 token 计,每百万输入 0.042 美元,输出不收钱。
上线前注意
- 题目用英文写,state 里的中文原文保留;state 的字段名就是题目里 Jev 引用上下文时用的变量名。
- 阈值要用自己 20–30 条真实数据校准,别照搬默认。
- 置信度低或 Noul 概率落在 0.5 附近的题,交给人或大模型复核,不要硬切分支。
- 这次要看图,请求头要加 TypeSafe-Danger-Zone-Images: true,图片宽高都要在 256–1568 像素之间,超出会直接报错;Box 题型现在只在 Jev 1.14 上有,模型升级前确认下还在不在。
真实调用
请求
curl https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  -H "TypeSafe-Danger-Zone-Images: true" \
  -d '{
  "model": "jev-1.14.0",
  "state": {
    "app": "聊天软件截图",
    "screenshot": "chat-shot"
  },
  "questions": {
    "last_sender": {
      "type": "choice",
      "instructions": "Who sent the latest (bottom-most) message in `screenshot`?",
      "criteria": {
        "them": "The other person (bubbles on the left)",
        "me": "Me (bubbles on the right)"
      }
    },
    "upset": {
      "type": "noul",
      "instructions": "Is the other person in `screenshot` upset with me?"
    },
    "input_box": {
      "type": "box",
      "instructions": "the message input box at the bottom of `screenshot`"
    }
  },
  "assets": {
    "chat-shot": {
      "type": "image",
      "format": "png",
      "data_base64": "<图片的 base64>"
    }
  }
}'import json, os, urllib.request
payload = json.loads("{\n \"model\": \"jev-1.14.0\",\n \"state\": {\n \"app\": \"聊天软件截图\",\n \"screenshot\": \"chat-shot\"\n },\n \"questions\": {\n \"last_sender\": {\n \"type\": \"choice\",\n \"instructions\": \"Who sent the latest (bottom-most) message in `screenshot`?\",\n \"criteria\": {\n \"them\": \"The other person (bubbles on the left)\",\n \"me\": \"Me (bubbles on the right)\"\n }\n },\n \"upset\": {\n \"type\": \"noul\",\n \"instructions\": \"Is the other person in `screenshot` upset with me?\"\n },\n \"input_box\": {\n \"type\": \"box\",\n \"instructions\": \"the message input box at the bottom of `screenshot`\"\n }\n },\n \"assets\": {\n \"chat-shot\": {\n \"type\": \"image\",\n \"format\": \"png\",\n \"data_base64\": \"<图片的 base64>\"\n }\n }\n}")
headers = {
"Authorization": "Bearer " + os.environ["TYPESAFE_API_KEY"],
"Content-Type": "application/json",
"TypeSafe-Danger-Zone-Images": "true",
}
req = urllib.request.Request(
"https://api.typesafe.ai/v1/systemone",
data=json.dumps(payload).encode("utf-8"),
headers=headers,
method="POST",
)
print(urllib.request.urlopen(req).read().decode("utf-8"))
返回
{
  "model": "jev-1.14.0",
  "answers": {
    "last_sender": {
      "type": "choice",
      "choice": "them",
      "confidence": 1,
      "probabilities": {
        "them": 1,
        "me": 0
      }
    },
    "upset": {
      "type": "noul",
      "noul": 0.95
    },
    "input_box": {
      "type": "box",
      "box": {
        "top": 0.92,
        "bottom": 0.98,
        "left": 0.04,
        "right": 0.83
      },
      "confidence": 0.89
    }
  },
  "usage": {
    "input_tokens": 3540,
    "output_tokens": 67
  }
}
人话解读
- Choice:选了 them,置信度 1.00
- Noul:「是」的概率 0.95
- Box:已框出,置信度 0.89