
文档目录
预先解析的值抽取
用正则找出候选的电子邮箱、电话号码和金额,再让 TypeSafe 选出问题所问的那段文本,让代码能规范化一个原样的值。
非官方中文翻译 · 内容以 英文原文 ↗ 为准 · 同步于 2026-10-15
正则找出候选值,TypeSafe 选出问题所问的那一个,代码按原样复制它。
这里的 find 和 pick 组合可以直接套用到你自己的文档上,下面三个示例展示用法:寄件人希望回执发往的地址、一个写成 +14155550177 的电话号码,以及被标记为扣款的发票总额 1315.50 USD。
TypeSafe 只会在你交给它的选项(option)中挑选,所以必须先把候选值找出来。正则负责找,TypeSafe 负责挑,代码负责把挑出的内容复制下来,分三步:
- 用正则找出文本中的候选值。把它调成宁可多找的设置。
- TypeSafe 挑出问题所问的那个候选值,并读出代码下游需要的属性(货币、国家、金额是抵扣还是扣款)。
- 代码把挑出的值原样复制下来并规范化。
因为 TypeSafe 只在正则找到的片段中做选择,所以拿回来的值就是其中的一个片段,原样复制。它不会凭空捏造一个值,也不会把数字写错。
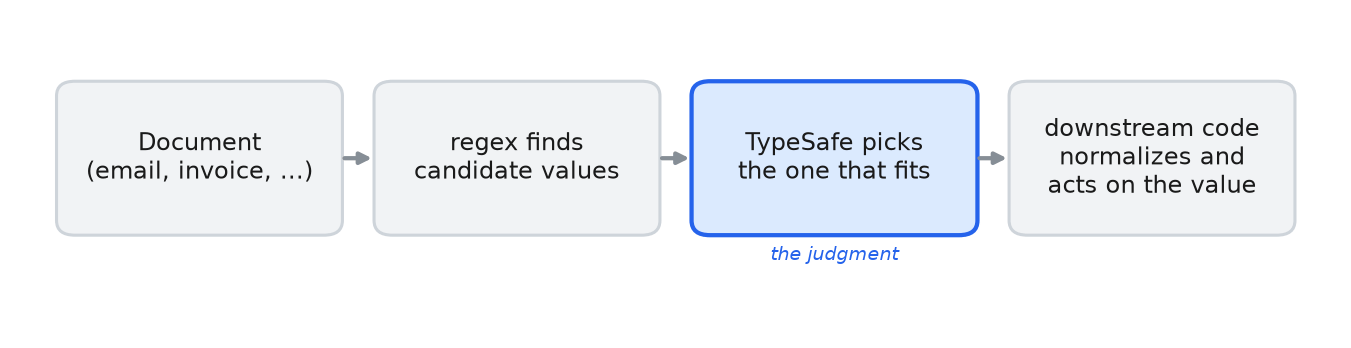
正则找出文档中的候选值,TypeSafe 挑出其中一个,下游代码把它规范化并执行相应操作。
环境配置
pip install ipython phonenumbers 'cooksafe>=0.2.0,<0.3.0'接着设置 TYPESAFE_API_KEY。
import os
import re
from decimal import Decimal
from pathlib import Path

import phonenumbers
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from typesafe_sdk import Choice, Noul, TypeSafeClient

TYPESAFE_MODEL = "jev-1.12"
NONE = "none"  # the escape hatch on every selection: "none of the candidates fits"

# base_url defaults to https://api.typesafe.ai/ ; the env override points at another deployment.
ts = TypeSafeClient(
    api_key=os.environ.get(
        "TYPESAFE_API_KEY", "cache-only"
    ),  # cached re-renders need no key
    base_url=os.environ.get("TYPESAFE_BASE_URL"),
    timeout=30.0,
)
json_cache = JsonCache(Path("json_cache.json"))
辅助函数
find 运行一个调成宁可多找的正则,并对匹配结果去重。pick 是一个 Choice(选择题)问题,其选项(option)就是 find 返回的片段,所以它的答案(answer)就是这些片段中按原样复制的那一个,没有候选匹配时为 none。classify 是一个 Choice 问题,作用于一组固定标签,这里用来选货币和国家。is_true 是一个 Noul(是非题),这里用来判断一笔金额是否为抵扣。
每次调用都会缓存到 json_cache.json,所以重新渲染不会发起 API 请求。
EMAIL_RE = re.compile(r"[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}")
PHONE_RE = re.compile(r"\(?\+?\d[\d\s()\-.]{6,}\d")
MONEY_RE = re.compile(r"[$€£¥]\s?\d[\d,]*(?:\.\d{2})?")


def find(pattern: re.Pattern, text: str) -> list[str]:
    """Code-side candidate finder: recall-tuned regex, deduped, in document order."""
    seen: set[str] = set()
    out: list[str] = []
    for match in pattern.findall(text):
        span = match.strip()
        if span and span not in seen:
            seen.add(span)
            out.append(span)
    return out


@json_cache
def pick(document: str, candidates: list[str], question: str) -> dict:
    """TypeSafe selects which found span plays the role. Returns {choice, confidence}.

    The options ARE the candidate spans, so ``choice`` is a verbatim copy of one of them (or the
    ``none`` hatch) - the model chooses, code owns the string."""
    criteria = {c: None for c in candidates} | {
        NONE: "None of these is the requested value."
    }
    answer = ts.system_one(
        state=document,
        questions={"pick": Choice(instructions=question, criteria=criteria)},
        model=TYPESAFE_MODEL,
    ).answers["pick"]
    return {"choice": answer.choice, "confidence": answer.confidence}


@json_cache
def classify(document: str, question: str, options: list[str]) -> dict:
    """A small Choice over a fixed label set (currency, country, ...). Returns {choice, confidence}."""
    answer = ts.system_one(
        state=document,
        questions={
            "q": Choice(instructions=question, criteria={o: None for o in options})
        },
        model=TYPESAFE_MODEL,
    ).answers["q"]
    return {"choice": answer.choice, "confidence": answer.confidence}


@json_cache
def is_true(document: str, question: str) -> float:
    """A yes/no Noul. Returns P(yes)."""
    return (
        ts.system_one(
            state=document,
            questions={"q": Noul(instructions=question)},
            model=TYPESAFE_MODEL,
        )
        .answers["q"]
        .noul
    )
邮箱:按角色挑出正确的地址
邮件头里有四个地址。正文要求回执发到个人邮箱,而不是 To: 里的账单别名,所以答案得读完正文才知道。这里有两个问题:哪个地址接收回执,以及哪个地址发送了这封邮件。
EMAIL_DOC = """From: Dana Whit <dana.whit@acme-corp.com>
To: billing@acme-corp.com
Cc: orders@acme-corp.com
Reply-To: dana.personal@gmail.com

Hi team - please don't use the billing alias for this one. Send my receipt to my
personal address instead. Thanks, Dana."""

emails = find(EMAIL_RE, EMAIL_DOC)
receipt = pick(
    EMAIL_DOC, emails, "Which email address does the sender want their receipt sent to?"
)
sender = pick(
    EMAIL_DOC, emails, "Which email address did this message come from (the From line)?"
)

print("candidates :", emails)
# code copies the picked value verbatim and normalizes (lowercase); it never re-types it
print(
    f"receipt -> : {receipt['choice'].lower():<28} (conf {receipt['confidence']:.2f})"
)
print(f"sender -> : {sender['choice'].lower():<28} (conf {sender['confidence']:.2f})")candidates : ['dana.whit@acme-corp.com', 'billing@acme-corp.com', 'orders@acme-corp.com', 'dana.personal@gmail.com']
receipt -> : dana.personal@gmail.com (conf 0.98)
sender -> : dana.whit@acme-corp.com (conf 1.00)receipt 是 Reply-To: 行上的个人 Gmail 地址,这正是正文所要求的;sender 是 From 行上的那个。两者都是正则匹配结果的复制,代码再把它转成小写。
电话:挑出手机号并规范化为 E.164
有三个号码,都没有带国家代码。TypeSafe 挑出手机号,并从文本中读出国家;phonenumbers 把这两个答案组合成 E.164,也就是以 + 加国家代码开头的国际格式。
PHONE_DOC = """Reach our San Francisco office at these numbers: main desk (415) 555-0199,
billing fax (415) 555-0142, and my direct cell (415) 555-0177. Call the cell if it's urgent."""

phones = find(PHONE_RE, PHONE_DOC)
mobile = pick(PHONE_DOC, phones, "Which of these is the direct mobile / cell number?")
region = classify(
    PHONE_DOC,
    "In what country is this office located?",
    ["US", "GB", "DE", "FR", "CA", "AU"],
)

# code copies the picked value and normalizes it with the model-supplied country
parsed = phonenumbers.parse(mobile["choice"], region["choice"])
e164 = phonenumbers.format_number(parsed, phonenumbers.PhoneNumberFormat.E164)

print("candidates :", phones)
print(f"mobile  -> : {mobile['choice']}  (conf {mobile['confidence']:.2f})")
print(f"country -> : {region['choice']}  (conf {region['confidence']:.2f})")
print(f"E.164 -> : {e164}")candidates : ['(415) 555-0199', '(415) 555-0142', '(415) 555-0177']
mobile -> : (415) 555-0177 (conf 1.00)
country -> : US (conf 0.90)
E.164 -> : +14155550177这些数字本身并没有说明哪个是手机号,也看不出它在哪个国家;周围的文字才能看出来。TypeSafe 读这些文字,phonenumbers 把挑出的号码格式化成 +14155550177。
金额:挑出金额、识别货币、标记抵扣与扣款
一张发票上共有四个金额。TypeSafe 挑出应付总额和抵扣金额,读出货币,并把每个挑出的金额标记为扣款或抵扣。代码把每个挑出的字符串原样复制下来,并解析为一个 Decimal。
MONEY_DOC = """Invoice INV-2087.
Subtotal: $1,200.00
Sales tax: $115.50
Total due: $1,315.50
A $50.00 courtesy credit from last month has already been applied."""

amounts = find(MONEY_RE, MONEY_DOC)
currency = classify(
    MONEY_DOC,
    "What currency are these amounts in?",
    ["USD", "EUR", "GBP", "JPY", "CAD"],
)
total = pick(MONEY_DOC, amounts, "Which amount is the total the customer must pay?")
credit = pick(
    MONEY_DOC, amounts, "Which amount is the courtesy credit that was applied?"
)


def to_decimal(value: str) -> Decimal:
    """Copy the picked value and parse the number in code (US grouping/decimal here)."""
    return Decimal(re.sub(r"[^\d.]", "", value))


for label, chosen in [("total due", total), ("credit", credit)]:
    is_credit = is_true(
        MONEY_DOC,
        f"Is the amount {chosen['choice']} a credit or refund to the customer, not a charge?",
    )
    kind = "credit" if is_credit > 0.5 else "charge"
    print(
        f"{label:<10}: {chosen['choice']:<10} -> {to_decimal(chosen['choice'])} {currency['choice']} "
        f"({kind}, P(credit)={is_credit:.2f})"
    )
print("\ncandidates :", amounts)total due : $1,315.50 -> 1315.50 USD (charge, P(credit)=0.01)
credit : $50.00 -> 50.00 USD (credit, P(credit)=0.99)
candidates : ['$1,200.00', '$115.50', '$1,315.50', '$50.00']应付总额是 $1,315.50,抵扣金额是 $50.00,都是 USD。抵扣还是扣款的 Noul 在总额上回答 0.01,在抵扣上回答 0.99,因此代码能知道每个解析出来的 Decimal 的符号。
to_decimal默认假设逗号是千分位分隔符、点是小数点。这对$1,315.50成立,但对€1.315,50就反过来了。可以用一个Noul问题询问文档采用的是哪种约定,并在代码里按情况分支。
在 TypeSafe playground 中打开
一个分享链接,能在浏览器中打开邮件线程,其中带有收据问题,以及正则所找到的四个地址作为它的选项。
receipt_criteria = {e: None for e in emails} | {
    NONE: "None of these is the requested value."
}
playground_link = make_playground_link(
    EMAIL_DOC,
    {
        "receipt": Choice(
            instructions="Which email address does the sender want their receipt sent to?",
            criteria=receipt_criteria,
        )
    },
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open this thread + selection in the TypeSafe playground]({playground_link})"
    )
)
Open this thread + selection in the TypeSafe playground →
两个限制
- 一个
Choice问题最多允许 255 个选项。如果候选超过这个数量,分两阶段收窄:先选段落,再选段落内的片段。 - 找候选是最费工夫的部分。邮箱、电话号码和金额都有正则可以覆盖;而姓名没有,所以姓名候选只能来自你已有的名单、命名实体识别器,或者由 LLM 来提出。之后 TypeSafe 会按问题的要求挑出正确的那一个。
本文档由 Mintlify 构建和托管,这是一个开发者文档平台。