
文档目录
重排序
为 40 条 CLERC 法律查询各构建 30 篇文档的 BM25 候选短列表,再为每个「查询-候选」对使用一个 TypeSafe 问题(question),将 top-1 准确率从 5% 提升到 18%,top-10 准确率从 38% 提升到 62%。
非官方中文翻译 · 内容以 英文原文 ↗ 为准 · 同步于 2026-10-15
你有成千上万份文档,需要从中找出能回答某个特定问题的那一份。那么该怎么找?
第一步,使用一种足够快的方法(例如关键词匹配)把成千上万的候选缩减到一个看起来有可能的候选短列表。我们把这一步称为 fast search(快速检索)。
Fast search 在这一步很有效,但它无法告诉你短列表中哪一个候选才是正确答案。这正是 re-ranking(重排序)的用武之地:它针对查询逐一为短列表上的每个候选打分,并把得分最高的那一个排到最前面。
下面在 CLERC 数据集的 3,565 篇法院判决文书片段上同时运行这两步:BM25 为 40 条查询各构建一个包含 30 个候选的 fast search 短列表,然后 TypeSafe 对每条短列表进行重排序。经过重排序后,正确片段在 18% 的查询中位列第一,而仅靠 fast search 时这一比例只有 5%。
在这个过程中,你将了解:
- fast search 能做什么,以及为什么它并不能解决所有问题
- 什么是 re-ranking(重排序),以及它如何衔接在 fast search 之后
- TypeSafe 如何针对一条查询对单个候选打分,以及这种做法能将结果提升多少
自己动手试一试
在 TypeSafe Playground 中打开一条 query、一个候选以及一个重排序问题
如何在成千上万份文档中找出需要的那一份?
你面前堆着一摞文档,外加一条 query——一段描述你正在寻找什么的文本。文档堆里藏着能回答这条 query 的那一份。
逐个把文档和 query 比较当然可行,每份文档一次比较:数百万份文档意味着每条 query 要做数百万次比较。你可以用一种两步法来提升性能:
- 用一种足够快、能跑遍整摞文档的方法,把文档堆缩减到一个候选短列表。
- 对这个短列表应用更准确的一步,从中找出唯一正确的答案。

本 cookbook 在一组法院判决文书数据上对这套方案进行实测,详见下面的 一个重排序示例。
什么是 fast search?
Fast search 是任何一种能够把一条 query 和大型文档库中的每份文档都做比较、并快速返回一个排序好的候选短列表的方法。常见做法包括基于关键词的检索(例如 BM25),以及基于稠密向量(dense embedding)的语义比对。实际系统中往往把两种方法结合使用。
本 cookbook 的第一步只采用 BM25,不再叠加其它手段。BM25 通过文档与查询之间共享的词语来对片段进行排序。把这一步保持简单,是为了把注意力留给 re-ranking(重排序)——这才是本 cookbook 的重点。至于 fast search 具体用哪种方法,其实是一个旁支问题:re-ranking 看到的只是那些进入候选短列表的片段。
什么是 re-ranking?
Re-ranking 接收 fast search 已经生成的短列表,并把它重新排成更合理的顺序。它不再一次性地把 query 和整个文档库做比较,而是逐一把 query 和短列表上的每个候选进行比对,并按这个分数对短列表排序。
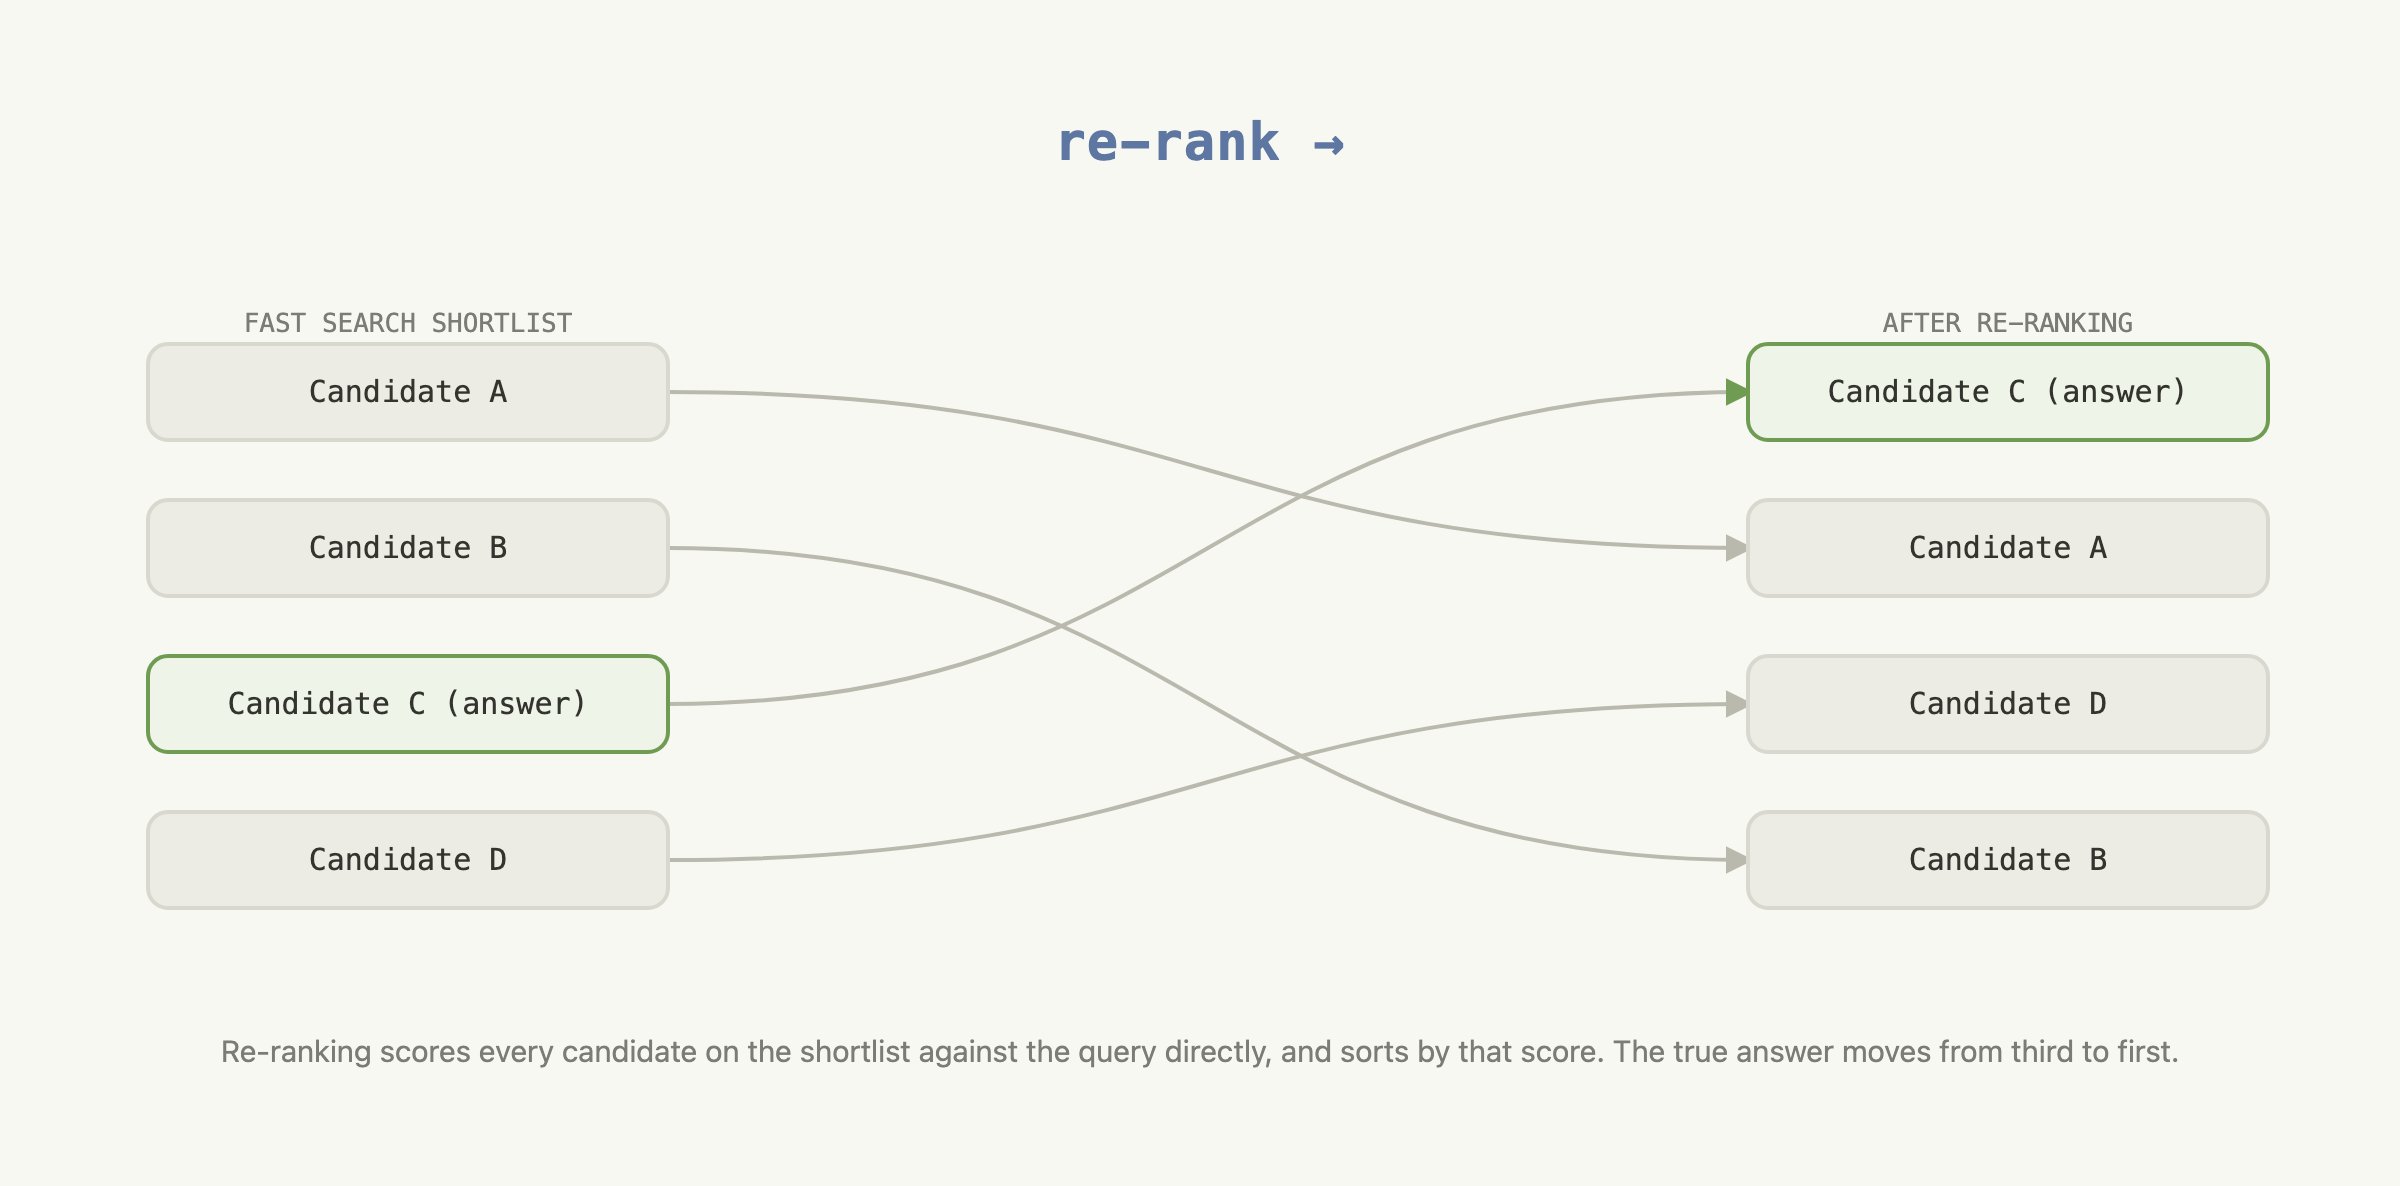
这个分数可以由一个语言模型给出:把 query 和一个候选一起交给模型,让它判断这个候选在多大程度上回答了这条 query。这样一来,即便候选的措辞与 query 不一致,re-ranking 也能在短列表中找到最佳匹配。
使用 TypeSafe 进行重排序
Re-ranker 需要为每一对「query-候选」都产出一个可比的分数。通用语言模型既可以直接产出这些分数,也可以直接对整条短列表排序。但要做每对相互独立的打分,就得自行定义一套评分量表,并指示模型对每个候选都按同一个标准执行。即便如此,重复调用同一对内容仍可能给出不同的分数;而通用生成模型在这种只需要一个数字的任务上,又会带来额外的时延和成本。
TypeSafe 的返回值
借助 TypeSafe,这个打分请求可以保持为一个 yes/no 问题:
Could this candidate passage be from the cited precedent?仅靠单纯的 yes 或 no 还不足以给 30 个候选排序。使用 Noul(非是题) 作为替代,它会返回一个介于 0 到 1 之间的数字,称为 noul。这个 noul 就是 TypeSafe 对「答案为 yes」的概率估计。
这道 question 的 criteria(判定标准)定义了何为 true、何为 false。TypeSafe 把 criteria 应用到每一对「query-候选」上,并直接返回 noul。这个 noul 就是应用程序用来排序的分数。你不需要为通用模型额外设计一套评分量表,而 TypeSafe 本身就为这种重复打分做了更快速、成本更低、更一致的优化。
用一段简化的伪代码表示,一次 TypeSafe 打分调用大致是这样的:
question = Noul(
    instructions="Is this candidate the cited case?",
    criteria=NoulCriteria(
        true="The candidate states the specific rule the query cites.",
        false="The candidate is only on a similar topic.",
    ),
)
response = client.system_one(state={...}, questions={"is_cited_source": question})
response.answers["is_cited_source"].noul  # -> 0.87
TypeSafe 把 query 和单个候选一起交给这道 question 来读,并返回一个 noul。
你可以用这种方式重排一条短列表:对短列表上的每个候选都跑同一道 question,然后按每次调用返回的 noul 从高到低排序。
nouls = {candidate: ask_typesafe(query, candidate) for candidate in shortlist}
reranked = sorted(shortlist, key=lambda c: nouls[c], reverse=True)  # highest noul first
下面的示意图展示了如何为每个候选各发起一次请求,从而拿到用于重排短列表的那些分数。
flowchart LR
    q["query excerpt<br/><i>one opinion passage,<br/>citation removed</i>"]
    sl["shortlist from fast search<br/><i>30 candidate passages</i>"]
    quest["<b>one Noul</b><br/>could this candidate be<br/>from the cited precedent?<br/><i>criteria fix true and false</i>"]

    %% direction LR inside an LR chart keeps each state beside its noul, two columns,
    %% so the fan-out is four rows tall instead of eight
    subgraph fan["one request per candidate · no request sees another"]
        direction LR
        d1["state<br/>{query, candidate 1}"] --> n1["noul<br/>0.87"]
        d2["state<br/>{query, candidate 2}"] --> n2["noul<br/>0.41"]
        dx["⋮"] --> nx["⋮"]
        d30["state<br/>{query, candidate 30}"] --> n30["noul<br/>0.12"]
    end

    sort["sort by noul,<br/>highest first"]
    out["re-ranked shortlist<br/><i>same 30, better order</i>"]

    q --> fan
    sl --> fan
    quest --> fan
    fan --> sort --> out

    %% the elision is not a node - drop its box so it reads as "and so on"
    classDef elide fill:none,stroke:none
    class dx,nx elide
    linkStyle 2 stroke:none
一个重排序示例
快速搜索与重排序目前在 CLERC(一个法律检索数据集)上运行。本示例使用 3,565 篇法庭意见段落和 40 个查询。
准备工作
首先安装本教程所依赖的包。
bm25s和datasets用于构建快速搜索的候选短名单。typesafe-sdk和cooksafe负责重排序与 API 缓存。matplotlib用于绘制结果图表。
pip install bm25s datasets matplotlib 'cooksafe>=0.2.0,<0.3.0'下一段代码设置 TypeSafe 客户端与本教程后续将使用的常量,例如调用哪个 TypeSafe 模型,以及快速搜索交给重排序器的候选短名单大小。调用 TypeSafe 需要 TYPESAFE_API_KEY。
import hashlib
import json
import os
import random
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path

from cooksafe import JsonCache
from IPython.display import display
from typesafe_sdk import Noul, NoulCriteria, TypeSafeClient

TYPESAFE_MODEL = "jev-1.12"
PRICE = (
    0.042,
    0.00,
)  # $ per 1M tokens (input, output); TypeSafe jev-1.12 as of 2026-08
N_ROWS = 170  # CLERC rows pooled into the shared corpus
N_QUERIES = 40  # rows we evaluate
TOP_K = 30  # candidates the shortlist hands to the re-ranker, per query

client = TypeSafeClient(
    api_key=os.environ.get(
        "TYPESAFE_API_KEY", "cache-only"
    ),  # keyless kernels replay the cache
    base_url=os.environ.get("TYPESAFE_ENDPOINT"),
    timeout=120.0,
)
json_cache = JsonCache(Path("json_cache.json"))
用快速搜索为段落排序
此处使用的数据集是一份美国法庭意见语料库,由 170 条数据合并而成。每条数据的结构如下:
- 查询(Query):一段去掉了某个引用的意见节选。
- 正确段落(Gold):被去掉的那个引用所指向的段落,也就是该查询唯一正确的答案。
- 候选段落(Candidates):语料库中的所有其他段落,每一段都是可能被错误地匹配到该查询上的。
在 170 条数据中,挑选 40 条作为评估用的查询。其余 130 条仅作为候选出现。
下一段代码构建候选短名单,采用上文所述的方法:
- 加载语料库。
- 用 BM25 对每个查询进行排序。
此处还没有用到 TypeSafe,这一步只是快速搜索。
CLERC_FILE = (
    "https://huggingface.co/datasets/jhu-clsp/CLERC/resolve/main/"
    "teva_train_dir/train_data.jsonl.gz"
)


def cid(text: str) -> str:
    """Corpus id: a content hash, so passages shared across queries dedupe."""
    return hashlib.sha1(text.encode("utf-8")).hexdigest()[:16]


@json_cache
def build_slice(n_rows: int, n_queries: int, seed: int) -> dict:
    """Stream CLERC rows, pool ``n_rows`` of them into a corpus, pick ``n_queries`` to evaluate."""
    from datasets import load_dataset  # heavy import, keep local

    stream = load_dataset("json", data_files=CLERC_FILE, streaming=True, split="train")
    rows = []
    for row in stream:
        if (
            row.get("positive_passages")
            and len(row.get("negative_passages") or []) == 20
        ):
            rows.append(row)
        if len(rows) >= 1000:
            break

    rng = random.Random(seed)
    picked = rng.sample(rows, n_rows)
    corpus, pool = {}, []
    for row in picked:
        gold = row["positive_passages"][0]["text"]
        corpus[cid(gold)] = gold
        for neg in row["negative_passages"]:
            corpus[cid(neg["text"])] = neg["text"]
        pool.append(
            {"qid": str(row["query_id"]), "query": row["query"], "gold": cid(gold)}
        )
    # hold out the first 20 pooled rows; evaluate on the rest
    queries = rng.sample(pool[20:], n_queries)
    # sort the corpus by id so every run — live or cache replay — iterates it identically
    return {"queries": queries, "corpus": dict(sorted(corpus.items()))}


def bm25_rankings(corpus: dict[str, str], queries: dict[str, str], k: int = 100):
    """Rank every passage in the corpus by word overlap with each query."""
    import bm25s

    cids = list(corpus)
    retriever = bm25s.BM25()
    retriever.index(bm25s.tokenize([corpus[c] for c in cids], stopwords="en"))
    qids = list(queries)
    idxs, _ = retriever.retrieve(
        bm25s.tokenize([queries[q] for q in qids], stopwords="en"), k=min(k, len(cids))
    )
    return {q: [cids[i] for i in idxs[row]] for row, q in enumerate(qids)}


def gold_rank(ranked: list[str], gold: str) -> int | None:
    """1-based rank of the gold id, or None if it isn't in the list."""
    return ranked.index(gold) + 1 if gold in ranked else None


SURFACE, INK, INK2, MUTED = "#f8f8f2", "#34342f", "#34342f", "#7c7c77"
GRID, AXIS, BLUE, GREEN = "#d8d8cf", "#d8d8cf", "#5d76a2", "#6f9b52"


def bar_chart(labels: list[str], shares: list[float], title: str) -> None:
    """A small single-series bar chart of shares (0-1, shown as percentages)."""
    import matplotlib.pyplot as plt

    fig, ax = plt.subplots(figsize=(5, 3.2), facecolor=SURFACE)
    ax.set_facecolor(SURFACE)
    for side in ("top", "right"):
        ax.spines[side].set_visible(False)
    for side in ("left", "bottom"):
        ax.spines[side].set_color(AXIS)
    ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
    ax.set_axisbelow(True)
    ax.grid(axis="y", color=GRID, linewidth=0.8)

    bars = ax.bar(labels, shares, width=0.55, color=[BLUE, GREEN][: len(labels)])
    ax.bar_label(
        bars,
        labels=[f"{s * 100:.0f}%" for s in shares],
        padding=4,
        color=INK,
        fontsize=11,
    )
    ax.set_ylim(0, 1.1)
    ax.set_yticks([0, 0.25, 0.5, 0.75, 1.0])
    ax.set_yticklabels(["0%", "25%", "50%", "75%", "100%"])
    ax.set_ylabel(f"share of {len(queries)} queries", color=INK2, fontsize=9)
    ax.set_title(title, loc="left", color=INK, fontsize=11)
    plt.tight_layout()
    display(fig)
    plt.close(fig)


ds = build_slice(N_ROWS, N_QUERIES, seed=0)
corpus: dict[str, str] = ds["corpus"]
queries = {q["qid"]: q["query"] for q in ds["queries"]}
golds = {q["qid"]: q["gold"] for q in ds["queries"]}

candidates = {q: ranked[:TOP_K] for q, ranked in bm25_rankings(corpus, queries).items()}

in_top_k = sum(golds[q] in candidates[q] for q in queries)
at_rank_1 = sum(candidates[q][0] == golds[q] for q in queries)

bar_chart(
    [f"In top {TOP_K}", "At rank 1"],
    [in_top_k / len(queries), at_rank_1 / len(queries)],
    f"Where the correct passage lands, {len(queries)} queries against {len(corpus):,} candidates",
)
快速搜索不太可能把正确段落排在第一位
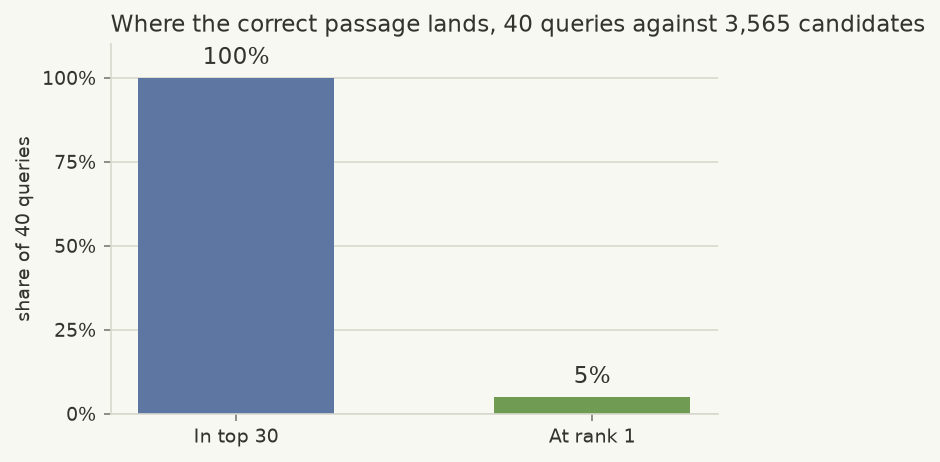
图表展示了快速搜索在 3,565 个候选中把正确段落放在了哪里。
快速搜索能够稳定地把语料库缩减到一份包含正确答案的候选短名单。在全部 40 个查询中,它都包含正确答案。但该段落很少是短名单中的第一名——只有 5% 的概率。
接下来的重排序只对已经在候选短名单上的前 30 个候选进行重新排序,无法补上快速搜索没有选中的段落。本例中,候选短名单对全部 40 个查询都包含了正确段落,因此重排序可以专心把每一篇都排到更好的位置。
用 TypeSafe 完成重排序
重排序会对候选短名单中的每个候选就其查询打分,然后按分数排序。TypeSafe 对每一对(查询、候选)所提的问题是:该候选是否可能就是该查询所去掉的引用所指向的段落。
下一段代码完成以下步骤:
- 定义这个问题。
- 对每个候选短名单中的每个候选各调用一次,40 个查询乘以 30 个候选,总共 1,200 次调用,并发运行,而不是按顺序一次接一次地执行。
- 按 TypeSafe 返回的分数对每个候选短名单排序,生成重排序结果。
is_cited_source = Noul(
    instructions=(
        "The query excerpt comes from a US federal court opinion and was written "
        "immediately around a citation to a precedent; the citation itself has been "
        "removed. Could the candidate passage be from that cited precedent — does it "
        "establish the specific legal proposition the query excerpt invokes at its "
        "citation point?"
    ),
    criteria=NoulCriteria(
        true=(
            "The candidate passage states or establishes the specific rule, standard, "
            "holding, or fact pattern that the query excerpt attributes to its removed "
            "citation."
        ),
        false=(
            "The candidate passage is merely on a similar topic or doctrine; it does not "
            "supply the specific proposition the query excerpt relies on."
        ),
    ),
)


@json_cache
def score_candidate(model: str, query: str, candidate: str, question_json: str) -> dict:
    """One TypeSafe call about one (query, candidate) pair: a noul, plus token usage."""
    # the SDK takes a question as its JSON dict, so the cached string decodes straight in
    question = json.loads(question_json)
    response = client.system_one(
        state={"query_excerpt": query, "candidate_passage": candidate},
        questions={"is_cited_source": question},
        model=model,
    )
    return {
        "noul": response.answers["is_cited_source"].noul,
        "input_tokens": response.usage.input_tokens or 0,
        "output_tokens": response.usage.output_tokens or 0,
    }


# Each of the 40 queries has 30 candidates, so re-ranking every shortlist means 1,200 independent
# calls — cheap enough to fire all at once with a thread pool instead of one after another.
pair_list = [(q, c) for q in queries for c in candidates[q]]
question_json = is_cited_source.model_dump_json(exclude_none=True)
with ThreadPoolExecutor(max_workers=12) as pool:
    results = pool.map(
        lambda p: score_candidate(
            TYPESAFE_MODEL, queries[p[0]], corpus[p[1]], question_json
        ),
        pair_list,
    )
pair_scores = {q: {} for q in queries}
for (q, c), result in zip(pair_list, results):
    pair_scores[q][c] = result

reranked = {
    q: sorted(candidates[q], key=lambda c: -pair_scores[q][c]["noul"]) for q in queries
}


def chart_before_after(
    runs: dict[str, dict[str, list[str]]], thresholds: list[int]
) -> None:
    """Grouped bar chart: how often the correct passage lands in the top N, for each run."""
    import numpy as np
    import matplotlib.pyplot as plt

    labels = list(runs)
    colors = [BLUE, GREEN]

    def share_in_top(rankings, k):
        return sum(
            gold_rank(rankings[q], golds[q]) in range(1, k + 1) for q in queries
        ) / len(queries)

    fig, ax = plt.subplots(figsize=(6.5, 3.6), facecolor=SURFACE)
    ax.set_facecolor(SURFACE)
    for side in ("top", "right"):
        ax.spines[side].set_visible(False)
    for side in ("left", "bottom"):
        ax.spines[side].set_color(AXIS)
    ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
    ax.set_axisbelow(True)
    ax.grid(axis="y", color=GRID, linewidth=0.8)

    x = np.arange(len(thresholds))
    width = 0.35
    for i, (label, rankings) in enumerate(runs.items()):
        shares = [share_in_top(rankings, k) for k in thresholds]
        offset = (i - (len(labels) - 1) / 2) * width
        bars = ax.bar(x + offset, shares, width * 0.92, color=colors[i], label=label)
        ax.bar_label(
            bars,
            labels=[f"{s * 100:.0f}%" for s in shares],
            padding=3,
            color=INK2,
            fontsize=8.5,
        )

    ax.set_xticks(x, [f"top {k}" for k in thresholds])
    ax.set_ylim(0, 1)
    ax.set_yticks([0, 0.25, 0.5, 0.75, 1.0])
    ax.set_yticklabels(["0%", "25%", "50%", "75%", "100%"])
    ax.set_ylabel(f"share of {len(queries)} queries", color=INK2, fontsize=9)
    ax.set_title(
        "How often the correct passage lands near the top",
        loc="left",
        color=INK,
        fontsize=11,
    )
    ax.legend(frameon=False, labelcolor=INK2, fontsize=9, loc="upper left")
    plt.tight_layout()
    display(fig)
    plt.close(fig)


chart_before_after(
    {"Fast search": candidates, "+ TypeSafe re-rank": reranked}, [1, 5, 10]
)

calls = [pair_scores[q][c] for q in queries for c in pair_scores[q]]
input_tokens = sum(call["input_tokens"] for call in calls)
output_tokens = sum(call["output_tokens"] for call in calls)
cost = input_tokens / 1_000_000 * PRICE[0] + output_tokens / 1_000_000 * PRICE[1]
print(
    f"{len(calls)} TypeSafe calls used {input_tokens:,} input and "
    f"{output_tokens:,} output tokens, costing ${cost:.4f}."
)1200 TypeSafe calls used 1,536,002 input and 25,200 output tokens, costing $0.0645.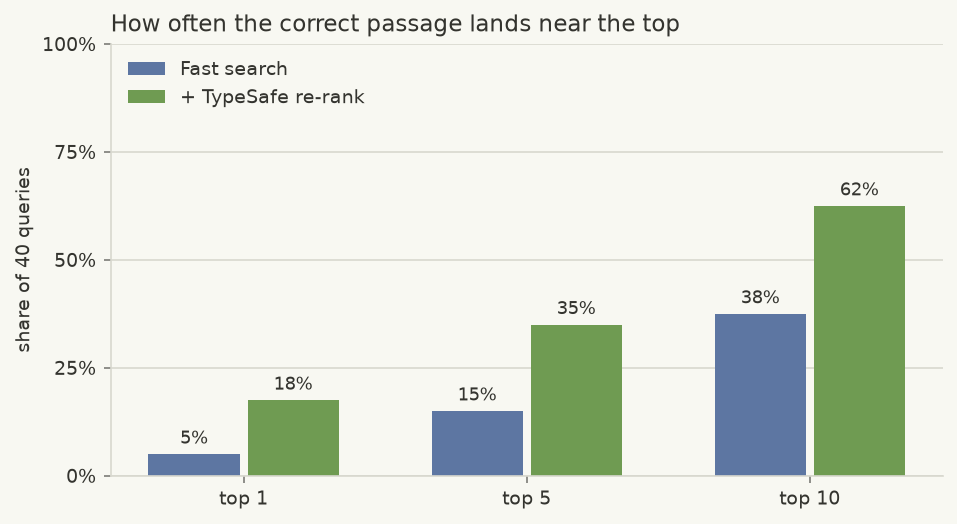
重排序将正确答案往顶部推
图表在三个阈值上对比了快速搜索与加上重排序之后的快速搜索。每个阈值下,重排序都把正确段落排得更靠前:
- Top 1 — 5% → 18%
- Top 5 — 15% → 35%
- Top 10 — 38% → 62%
报告的 token 用量和费用覆盖了用于为全部 40 个候选短名单重排序的 1,200 次 TypeSafe 调用。
每条 CLERC 数据包含一篇正确段落与 20 篇负例段落。本教程把这 170 条数据的段落汇总为一个共享语料库。对于 40 个评估查询中的每一个,BM25 都从整个语料库中选出 30 个候选,并不限于该数据自带的 20 篇负例。TypeSafe 接着读取查询与每个被选中的候选,对这 30 篇段落重新排序。
本教程为讲解清晰,对每对只问一个问题。真实应用中对同一对会在一次调用中问多个问题。参见 并行问题实战示例 与 推测式扇出(speculative fan-out)设计模式 以了解具体做法。
下一步
同样的构建模块也出现在 TypeSafe 文档的其他位置:
- Noul:介绍 TypeSafe 如何将一个是非题转换为分数。
- Speculative Fan-Out:用于在单次调用中针对同一份文档提出多个问题。
- Line-by-line Search:提供另一种按语义而非关键词搜索语料库的方式。
本文档由 Mintlify 构建和托管,这是一个开发者文档平台。