
文档目录
SDE(结构化数据抽取)级联
用一个 2 阶段的结构化数据抽取级联(mini → verify → reasoning),以小成本获得接近大型推理模型的质量。
非官方中文翻译 · 内容以 英文原文 ↗ 为准 · 同步于 2026-10-15
- 概述
- 大型推理模型抽取结构化数据效果不错,但速度慢、价格贵
- 小型模型便宜,但会出错
- 级联(cascade) 能以极小的成本获得接近最优的质量
- 我们使用的模型及其价格(每百万 token 的美元价格,输入 / 输出;标准价格
于 2026 年 9 月 15 日核对):
- 第 0 级(mini):
gpt-5.4-mini价格 $0.75 / $4.50 - 第 1 级(reasoning):
gpt-5.5价格 $5.00 / $30.00(约 mini 的 7 倍) - 验证器:TypeSafe
jev-1.12,价格 $0.042 / $0.00(输出 token 免费; Jev 公开定价)
- 第 0 级(mini):
- 算法
- 用便宜 / 小型模型进行 抽取(Extract)。
- 用 TypeSafe 题型做 验证(Verify):每个字段出一道 Noul(是非题)问题
- (例如「该值是否在源文档中缺失?」「它是否抄自无关文本?」),每道题返回出错概率 P。
- 如果验证器信号触发,就 升级(Escalate) 到昂贵的推理模型;否则保留便宜模型的答案。
- 本实战示例
- 端到端走完一个真实例子,然后展示在 100 个 prompt 上的权衡
- 注意:两个抽取级都使用 OpenAI 的文本模式
- 我们 不使用 结构化输出、工具调用或 json 模式,原因是:
- LLM 不太会 出现「遵循 schema」这类错误(这种错误很容易合成数据)
- 如果 LLM 真的没遵循 schema,那它通常已经相当混乱,所以约束解码解决不了底层问题
- 不过我们鼓励你亲自试试!
环境准备
- 安装依赖(TypeSafe 验证器客户端由 TypeSafe 的软件包源提供):
pip install openai datasets jsonschema ipython 'cooksafe>=0.2.0,<0.3.0'- 然后在环境中设置
OPENAI_API_KEY和TYPESAFE_API_KEY
import json
import os
from pathlib import Path

import jsonschema
from cooksafe import JsonCache, make_playground_link
from datasets import load_dataset
from IPython.display import Markdown, display
from openai import OpenAI
from typesafe_sdk import Noul, NoulCriteria, TypeSafeClient

MINI = "gpt-5.4-mini"  # rung 0: cheap + fast
REASONING = "gpt-5.5"  # rung 1: strong, run with reasoning_effort="high"
TS_MODEL = "jev-1.12"  # the TypeSafe verifier model
FIRE_T = 0.7  # escalate if any per-field P(wrong) exceeds this; also the "<== FIRES" display marker

oai = OpenAI()

ts = TypeSafeClient(api_key=os.environ["TYPESAFE_API_KEY"], timeout=30.0)
第 1 步:数据
我们选用 huggingface 上名为 scrapegraphai 的数据集
SCRAPEGRAPHAI_REVISION = "4bb9fba1dff9181c5acdb60a5a26fea62fa54fe9"
row = load_dataset(
    "scrapegraphai/scrapegraphai-100k",
    revision=SCRAPEGRAPHAI_REVISION,
    split="train",
)[516]
schema = json.loads(row["schema"])
prompt = row["prompt"]
content = row["content"]

print(
    f"""
PROMPT
===========
{prompt}

SCHEMA
===========
{json.dumps(schema, indent=2)}

CONTENT
===========
{content}
""".strip()
)PROMPT
===========
Find registration open date fall semester for New York University in New York, NY for the 2024-2025 school year.
SCHEMA
===========
{
"properties": {
"registration_open_date": {
"description": "The date that registration opens for the fall semester. MUST be in the format mm/dd/yyyy. For example, for a college in the 2024-2025 school year, it might be something like 09/05/2024. Return a blank string if you are unsure.",
"title": "Registration Open Date",
"type": "string"
},
"description": {
"description": "A brief description of the registration open date. For example, 'Registration opens for the fall semester'.",
"title": "Description",
"type": "string"
}
},
"required": [
"registration_open_date",
"description"
],
"title": "RegistrationOpen",
"type": "object"
}
CONTENT
===========
Skip to content Skip to current page navigation
[ ](https://www.nyu.edu/)
Search Site
[ ](https://www.nyu.edu/)
* [ Academics](https://www.nyu.edu/academics.html)
* [ Admissions](https://www.nyu.edu/admissions.html)
* [ Research](https://www.nyu.edu/research.html)
* [ University Life](https://www.nyu.edu/life.html)
* [ About](https://www.nyu.edu/about.html)
All NYU
# Mobile Navigation
[ ](https://www.nyu.edu/)
Search Site
* [Academics](https://www.nyu.edu/academics.html)
* [Admissions](https://www.nyu.edu/admissions.html)
* [Research](https://www.nyu.edu/research.html)
* [University Life](https://www.nyu.edu/life.html)
* [About](https://www.nyu.edu/about.html)
All NYU
Info for
* Back to main menu
* Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](http://home.nyu.edu/)
Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](https://home.nyu.edu/)
Search Site Search
# Events Calendar
Search Events
Apply Reset
* [About the Events Calendar ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar.html)
* [Events Calendar Tutorial ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar/tutorials.html)
* [Report issue or provide feedback ](https://nyu.service-now.com/sp?id=sc_cat_item&sys_id=7698dd2a98bcf4004c8c03063d84e274)
Search Filters Calendar
New York University
Equal Opportunity and Non-Discrimination at NYU - New York University is committed to maintaining an environment that encourages and fosters respect for individual values and appropriate conduct among all persons. In all University spaces--physical and digital--programming, activities, and events are carried out in accordance with applicable law as well as University policy, which includes but is not limited to its Non-Discrimination and Anti-Harassment Policy.
Unless otherwise noted, all content copyright New York University. All rights reserved.
* [Search](https://search.nyu.edu/)
* [Campus Map](https://www.nyu.edu/map.html)
* [Events](https://events.nyu.edu/)
* [Contact Us](https://www.nyu.edu/contact-us.html)
* [Give](https://www.nyu.edu/about/giving.html)
* [Copyright & Fair Use](https://www.nyu.edu/copyright-and-fair-use.html)
* [Privacy](https://www.nyu.edu/privacy.html)
* [Accessibility](https://www.nyu.edu/accessibility.html)
* [Feedback](https://www.nyu.edu/#feedback.html)
* [New York Campus](https://www.nyu.edu/)
* [Abu Dhabi Campus](https://nyuad.nyu.edu/)
* [Shanghai Campus](https://shanghai.nyu.edu/)
* [](https://facebook.com/)
* [](https://linkedin.com/)
* [](https://x.com/)
* [](https://instagram.com/)
* [](https://youtube.com/)- 这一行是 NYU 活动日历页面("Fall 2024 Census Date"):
- schema 只需要两个字段:
registration_open_date和description - 抓取到的内容只包含日历导航和样板文本:既没有注册日期,也没有描述
- 注意 schema 的
description字段甚至自带一个 示例 值("Registration opens for the fall semester"),写在字段描述里
- schema 只需要两个字段:
- 所以一个合格的抽取器应该 拒绝 编造页面中没有的字段
- 让我们看看小模型是否做对了!
第 2 步:用 mini 模型抽取(文本模式)
- 注意:
gpt-5.4-mini在这个输入上非常随机 —— 即使设置temperature=0,几乎每次运行都会编造出不同的description。为了完整演示可复现,我们 硬编码 下面整篇 notebook 要用到的那一个典型编造(验证器会以 P(wrong) > 0.8 标记它)。真实流水线里直接用extract(MINI, prompt, schema, content, temperature=0)即可。
EXTRACT_SYSTEM = (
    "You extract structured data from documents. Return only values supported by the text. "
    "Follow any value format specified by the schema or its field descriptions."
)


# LLM and TypeSafe calls are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering reproduces the published results with no API spend; delete the file to re-run live.
json_cache = JsonCache(Path("json_cache.json"))


@json_cache
def extract(
    model: str,
    prompt: str,
    schema: dict,
    content: str,
    *,
    reasoning_effort: str | None = None,
    temperature: float | None = None,
) -> dict:
    user = (
        f"{prompt}\n\nReturn ONLY a JSON object matching this JSON Schema:\n"
        f"{json.dumps(schema, indent=2)}\n\nDocument:\n{content}"
    )
    kwargs = {
        "model": model,
        "messages": [
            {"role": "system", "content": EXTRACT_SYSTEM},
            {"role": "user", "content": user},
        ],
    }
    if reasoning_effort:
        kwargs["reasoning_effort"] = reasoning_effort
    if temperature is not None:
        kwargs["temperature"] = temperature
    text = oai.chat.completions.create(**kwargs).choices[0].message.content
    # The prompt asks for ONLY a JSON object, so parse the reply as-is -- no regex fishing a
    # substring out of a malformed reply. If ``json.loads`` fails, treat it as an empty extraction
    # (the record-level analog of NaN): every field reads as absent, which the verifier flags and the
    # gate escalates -- the safe direction. Schema-following errors are rare here (see the overview).
    try:
        return json.loads(text)
    except (ValueError, json.JSONDecodeError):
        return {}


# Hard-coded canonical fabrication (see note above); a real pipeline would use extract(MINI, prompt, schema, content, temperature=0).
mini_record = {
    "registration_open_date": "",
    "description": "Registration opens for the fall semester",
}
print("mini extraction:\n", json.dumps(mini_record, indent=2))

# The record is a perfect fit for the JSON Schema -- and still wrong. Schema validation is necessary
# but not sufficient: it catches structural errors, never semantic ones. That gap is the whole point.
print("\nschema-valid:", jsonschema.Draft202012Validator(schema).is_valid(mini_record))mini extraction:
{
"registration_open_date": "",
"description": "Registration opens for the fall semester"
}
schema-valid: True- 这条记录是 符合 schema 的(上一行打印
True),但仍然是错的:registration_open_date留空,这与页面一致:页面没有给出日期- 但
description是编造的:页面根本没描述注册日期,mini 凭空捏造了一个听起来合理的值。它可能照搬 schema 自带的示例 "Registration opens for the fall semester",或者写一句 "...was not found in the document" - JSON-Schema 校验发现不了这类问题。小模型会自信地编造出满足 schema 的假数据,捕捉这些假数据正是语义验证器的工作
步骤 3:用 TypeSafe 验证
- 验证器是 TypeSafe;对每个字段我们构建一个
Noul问题:- 一个狭窄的是非题,设定为
true= 存在问题(升级)
- 一个狭窄的是非题,设定为
- TypeSafe 在一次 system_one 调用中按问题返回校准过的
noul=P(true) - 问题集:
- 一个整体的
__overall__::judge判定头("这条记录是否应该被升级?")。我们计算并展示它是为了把整条记录的判断与按字段的判定头进行对比,但第 4 步的门控 不使用它 —— 升级是由按字段的检测组驱动的。 - 一个按字段的检测组
- 非空字段获得完整的判定头集合
- 空字段(null / "" / [])只获得
absence_wrong判定头
- (完整流水线还为整个容器设置了一个
spurious判定头,以及一个整体的difficulty分数;这里不展示,以让本演练聚焦在两个门控判定头上)
- 一个整体的
- TypeSafe 之道:分解
- 注意所有内容都是 以编程方式分解 的,这就是 TypeSafe 的方式。
- 分解能让每个 prompt 都尽可能智能,并使算法可调、可解释。
# metric -> (question, NoulCriteria)
MAIN_QUESTIONS = {
    "name_desc_mismatch": (
        "Does the `extracted_field` fail to match the field at `path` or the `description` in the "
        "`field_spec`? If the `description` is empty, judge against the `path` alone.",
        NoulCriteria(
            true="the `extracted_field` does not match the field name or its `description`",
            false="the `extracted_field` matches the field name and `description`",
        ),
    ),
    "type_mismatch": (
        "Does the `extracted_field` violate the `type` declared in the `field_spec`?",
        NoulCriteria(
            true="the `extracted_field` violates the declared `type`",
            false="the `extracted_field` conforms to the declared `type`",
        ),
    ),
    "unreasonable": (
        "Is the `extracted_field` one that a reasonable person would not have extracted for this "
        "`field_spec`?",
        NoulCriteria(
            true="a reasonable person would not have extracted this value",
            false="the extraction is reasonable",
        ),
    ),
    "hallucinated": (
        "Is the `extracted_field` unsupported by, or absent from, the source text?",
        NoulCriteria(
            true="the `extracted_field` is a hallucination -- not supported by, or absent "
            "from, the source text",
            false="the `extracted_field` is supported by the source text",
        ),
    ),
    "off_target": (
        "Does the source text fail to genuinely report the thing the `field_spec` describes, so the "
        "value was pulled from incidental text?",
        NoulCriteria(
            true="the source does not genuinely provide this field -- the value was pulled "
            "from incidental text",
            false="the source genuinely reports this field",
        ),
    ),
    "incomplete": (
        "Does the `extracted_field` fail to capture a value the source supports (note whether the "
        "`field_spec` is `required`)?",
        NoulCriteria(
            true="the field is wrongly empty, null, or missing a value the source supports",
            false="the field captures the value the source supports",
        ),
    ),
    "format_violation": (
        "Does the `extracted_field` violate the format or constraints implied by the `description`, "
        "the schema `type`, and the extraction instructions (e.g. date format, units, enum membership)?",
        NoulCriteria(
            true="the `extracted_field` violates the implied format or constraints",
            false="the `extracted_field` satisfies the format and constraints",
        ),
    ),
}
ABSENCE_QUESTION = (
    "The `extracted_field` is empty, null, or an empty collection. Does the source text contain the "
    "information the `field_spec` describes, making the empty result wrong?"
)
ABSENCE_CRITERIA = NoulCriteria(
    true="a value was wrongly omitted", false="returning nothing is correct"
)

# The pipeline also asks one holistic, whole-record head: "should this be escalated?"
OVERALL_JUDGE = (
    "Is this extracted record an incorrect extraction -- some value unsupported by the source or "
    "not conforming to the schema, required information missing or wrong, or some field hallucinated -- "
    "so it should be escalated to a smarter model?"
)
OVERALL_JUDGE_CRITERIA = NoulCriteria(
    true="the record is an incorrect extraction",
    false="the record is a correct extraction",
)


def is_empty(v) -> bool:
    return v is None or (isinstance(v, (str, list, dict)) and len(v) == 0)


def field_spec(name: str) -> dict:
    """Minimal spec pulled from the schema (unwrapping anyOf/null for optional fields)."""
    p = schema["properties"][name]
    branches = p.get("anyOf") or []
    typ = p.get("type") or next(
        (b["type"] for b in branches if b.get("type") != "null"), "unknown"
    )
    return {
        "path": name,
        "type": typ,
        "description": p.get("description", ""),
        "required": name in schema.get("required", []),
    }


def build_questions(record: dict) -> dict[str, Noul]:
    """The verify question set: one holistic ``__overall__::judge`` head plus a per-field battery,
    keyed ``field::metric`` (mirrors build_verify_prompts)."""
    questions: dict[str, Noul] = {
        "__overall__::judge": Noul(
            instructions=OVERALL_JUDGE, criteria=OVERALL_JUDGE_CRITERIA
        ),
    }
    for name, value in record.items():
        spec = field_spec(name)
        if is_empty(value):
            questions[f"{name}::absence_wrong"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": ABSENCE_QUESTION,
                },
                criteria=ABSENCE_CRITERIA,
            )
            continue
        for metric, (question, criteria) in MAIN_QUESTIONS.items():
            if metric == "type_mismatch" and spec["type"] == "unknown":
                continue
            questions[f"{name}::{metric}"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": question,
                },
                criteria=criteria,
            )
    return questions


@json_cache
def verify(record: dict) -> dict[str, float | str]:
    """Run the whole Noul battery over a record in one TypeSafe call; return ``{field::metric: P(true)}``."""
    state = {
        "system_message": EXTRACT_SYSTEM,
        "instruction": "Extract the structured record from this document",
        "source_text": row["content"],
        "schema": schema,
        "extraction": record,
    }
    questions = build_questions(record)
    answers = ts.system_one(state=state, questions=questions, model=TS_MODEL).answers
    return {qid: ans.noul for qid, ans in answers.items()} | {
        "playground_link": make_playground_link(state, questions)
    }
对小型抽取运行整个检测组
checks = verify(mini_record)
playground_link = checks.pop("playground_link")
display(
    Markdown(
        f"🔗 [Open this verification in the TypeSafe playground]({playground_link})"
    )
)

print(f"{'qid':<40}{'P(wrong)':>9}")
print("-" * 50)
for fld, p in sorted(checks.items(), key=lambda c: -c[-1]):
    flag = "  <== FIRES" if p > FIRE_T else ""
print(f"{fld:<40}{p:>9.2f}{flag}")qid P(wrong)
--------------------------------------------------
description::hallucinated 0.95 <== FIRES
description::off_target 0.85 <== FIRES
description::unreasonable 0.58
__overall__::judge 0.56
description::incomplete 0.16
registration_open_date::absence_wrong 0.14
description::format_violation 0.10
description::name_desc_mismatch 0.08
description::type_mismatch 0.02- TypeSafe 把信号集中到真正出错的字段上。
- 我们的结果是校准过的:在出错的字段上高,在正确的字段上低,在看起来有问题但不能明确判定为错的字段上居中。
- 这就是一个 typesafe 验证器相对于粗暴的"整条记录好不好?"判断所能带来的好处
Step 4: 升级闸门
- 现在我们以
any_flag兜底:只要 任何 字段的 flag 超过FIRE_T(0.7,在上面设置,并与 Step 3 中的<== FIRES标记共用)就升级 - 这是一种
max风格的闸门(任一字段触发即升级),而非取平均——所以一个确定性的红灯就足够触发,而不会被平均成沉默
# any_flag is a per-field gate: the holistic __overall__ head is shown above but not part of it
fired = {
    qid: p
    for qid, p in checks.items()
    if not qid.startswith("__overall__") and p > FIRE_T
}
escalate = bool(fired)

print(
    f"any_flag gate (threshold {FIRE_T}): {'ESCALATE' if escalate else 'ACCEPT cheap result'}"
)
for qid, p in sorted(fired.items(), key=lambda c: -c[1]):
print(f" fired: {qid} (P={p:.2f})")any_flag gate (threshold 0.7): ESCALATE
fired: description::hallucinated (P=0.95)
fired: description::off_target (P=0.85)Step 5: 升级到推理模型
由于有信号触发,我们调用强模型(gpt-5.5,reasoning_effort="high")
final_record = (
    extract(REASONING, prompt, schema, content, reasoning_effort="high")
    if escalate
    else mini_record
)

print("mini      :", json.dumps(mini_record))
print("reasoning :", json.dumps(final_record))
print("\nfield-level diff (mini -> final):")
for name in mini_record:
    if mini_record[name] != final_record.get(name):
print(f" {name}: {mini_record[name]!r} -> {final_record.get(name)!r}")mini : {"registration_open_date": "", "description": "Registration opens for the fall semester"}
reasoning : {"description": "", "registration_open_date": ""}
field-level diff (mini -> final):
description: 'Registration opens for the fall semester' -> ''- 改进之处
- 推理模型丢弃了编造的
description,返回"" - 它识别出页面从未描述过注册日期,并拒绝凭空捏造
- 级联把一个「自信、符合 schema 的编造」变成了「诚实的空字段」
- 而且它只在 被验证器点了名 的这一项上花了推理模型的钱
- 推理模型丢弃了编造的
Step 6: 在 100 条 prompt 上的实际表现
- 这些是 TypeSafe 的内部结果,用上面的通用方法得到:
- 同一个
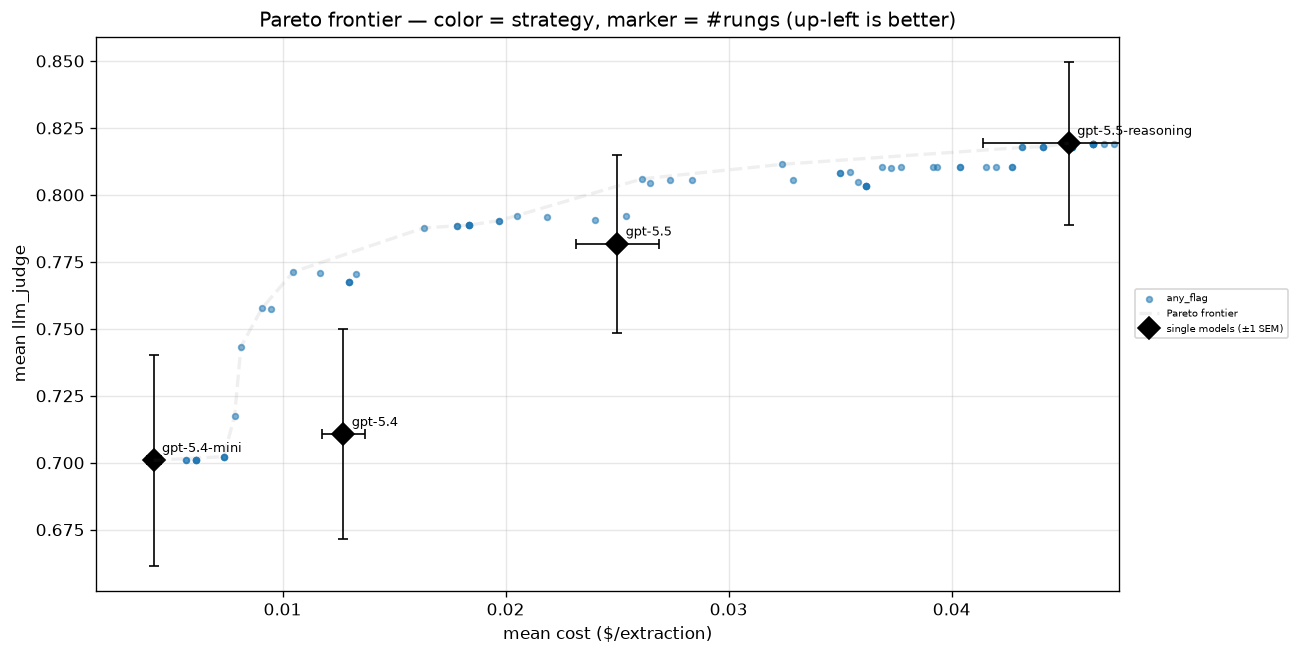
extract → verify → escalate循环,gpt-5.4-mini → gpt-5.5-reasoning,在每字段 head 上用any_flag闸门,在 100 条 scrapegraphai prompt 上跑一轮 - 每一项的廉价层抽取都由 TypeSafe 评分;闸门阈值("cut")从 0 扫到 1,每个配置都画到(成本,质量)空间中
- 图表是历史快照,其成本未按上方列出的当前 Jev 费率重新计算
- 同一个
- 如何读这张图:
- 黑色菱形 = 四个模型各自独立运行(成本随能力上升;最强的
gpt-5.5-reasoning位于右上方,质量 ≈0.81,单次抽取成本 ≈$0.10) - 蓝色点 = 不同闸门阈值下的级联;虚线是 Pareto 前沿(pareto frontier)
- 级联前沿 位于所有单个模型的左上方:扫一遍闸门就能以一小部分成本获得顶级模型的大部分质量
- 廉价层近乎免费地处理简单项,被标记的项才需要支付推理模型的费用
- 黑色菱形 = 四个模型各自独立运行(成本随能力上升;最强的
Appendix A: 什么是好的验证器信号
- 级联好不好完全取决于验证器;区分有用信号和无用信号的标准是:
- 窄而接地。
- 针对源文本、针对单个字段的一个可检查的是/否问题(例如「这个值在源文本中是否缺失?」),而不是含糊的「这次抽取好不好?」
- 含糊的问题会给出含糊、且未校准过的分数
- 坏 = TRUE,并写出明确的判定标准(criteria)。
- 设计问题时让 升级 的情况对应
true,并明确说明true/false各自的含义
- 设计问题时让 升级 的情况对应
- 先按字段分析,再用
max聚合。- 按字段的 flag 能定位错误,并保持稀疏和强劲
max(「任一 flag 触发」)保证一个确定性的红灯就能升级,而不会被平均成沉默
- 独立且廉价。
- 一个独立的验证器(这里是 TypeSafe)来评判输出,能补上抽取器自身的盲点
- 它必须足够廉价,否则也就没什么节省空间了
- 可区分 / 已校准。
- 好的信号在真实错误上是高的、在正确答案上是低的,因此单一阈值就能干净地切分「接受 vs 升级」
- 这种区分度正是把 Pareto 曲线推向左上方的原因
- 窄而接地。
本文档由 Mintlify 构建和托管。Mintlify 是一个面向开发者的文档平台。